ExtractThinker
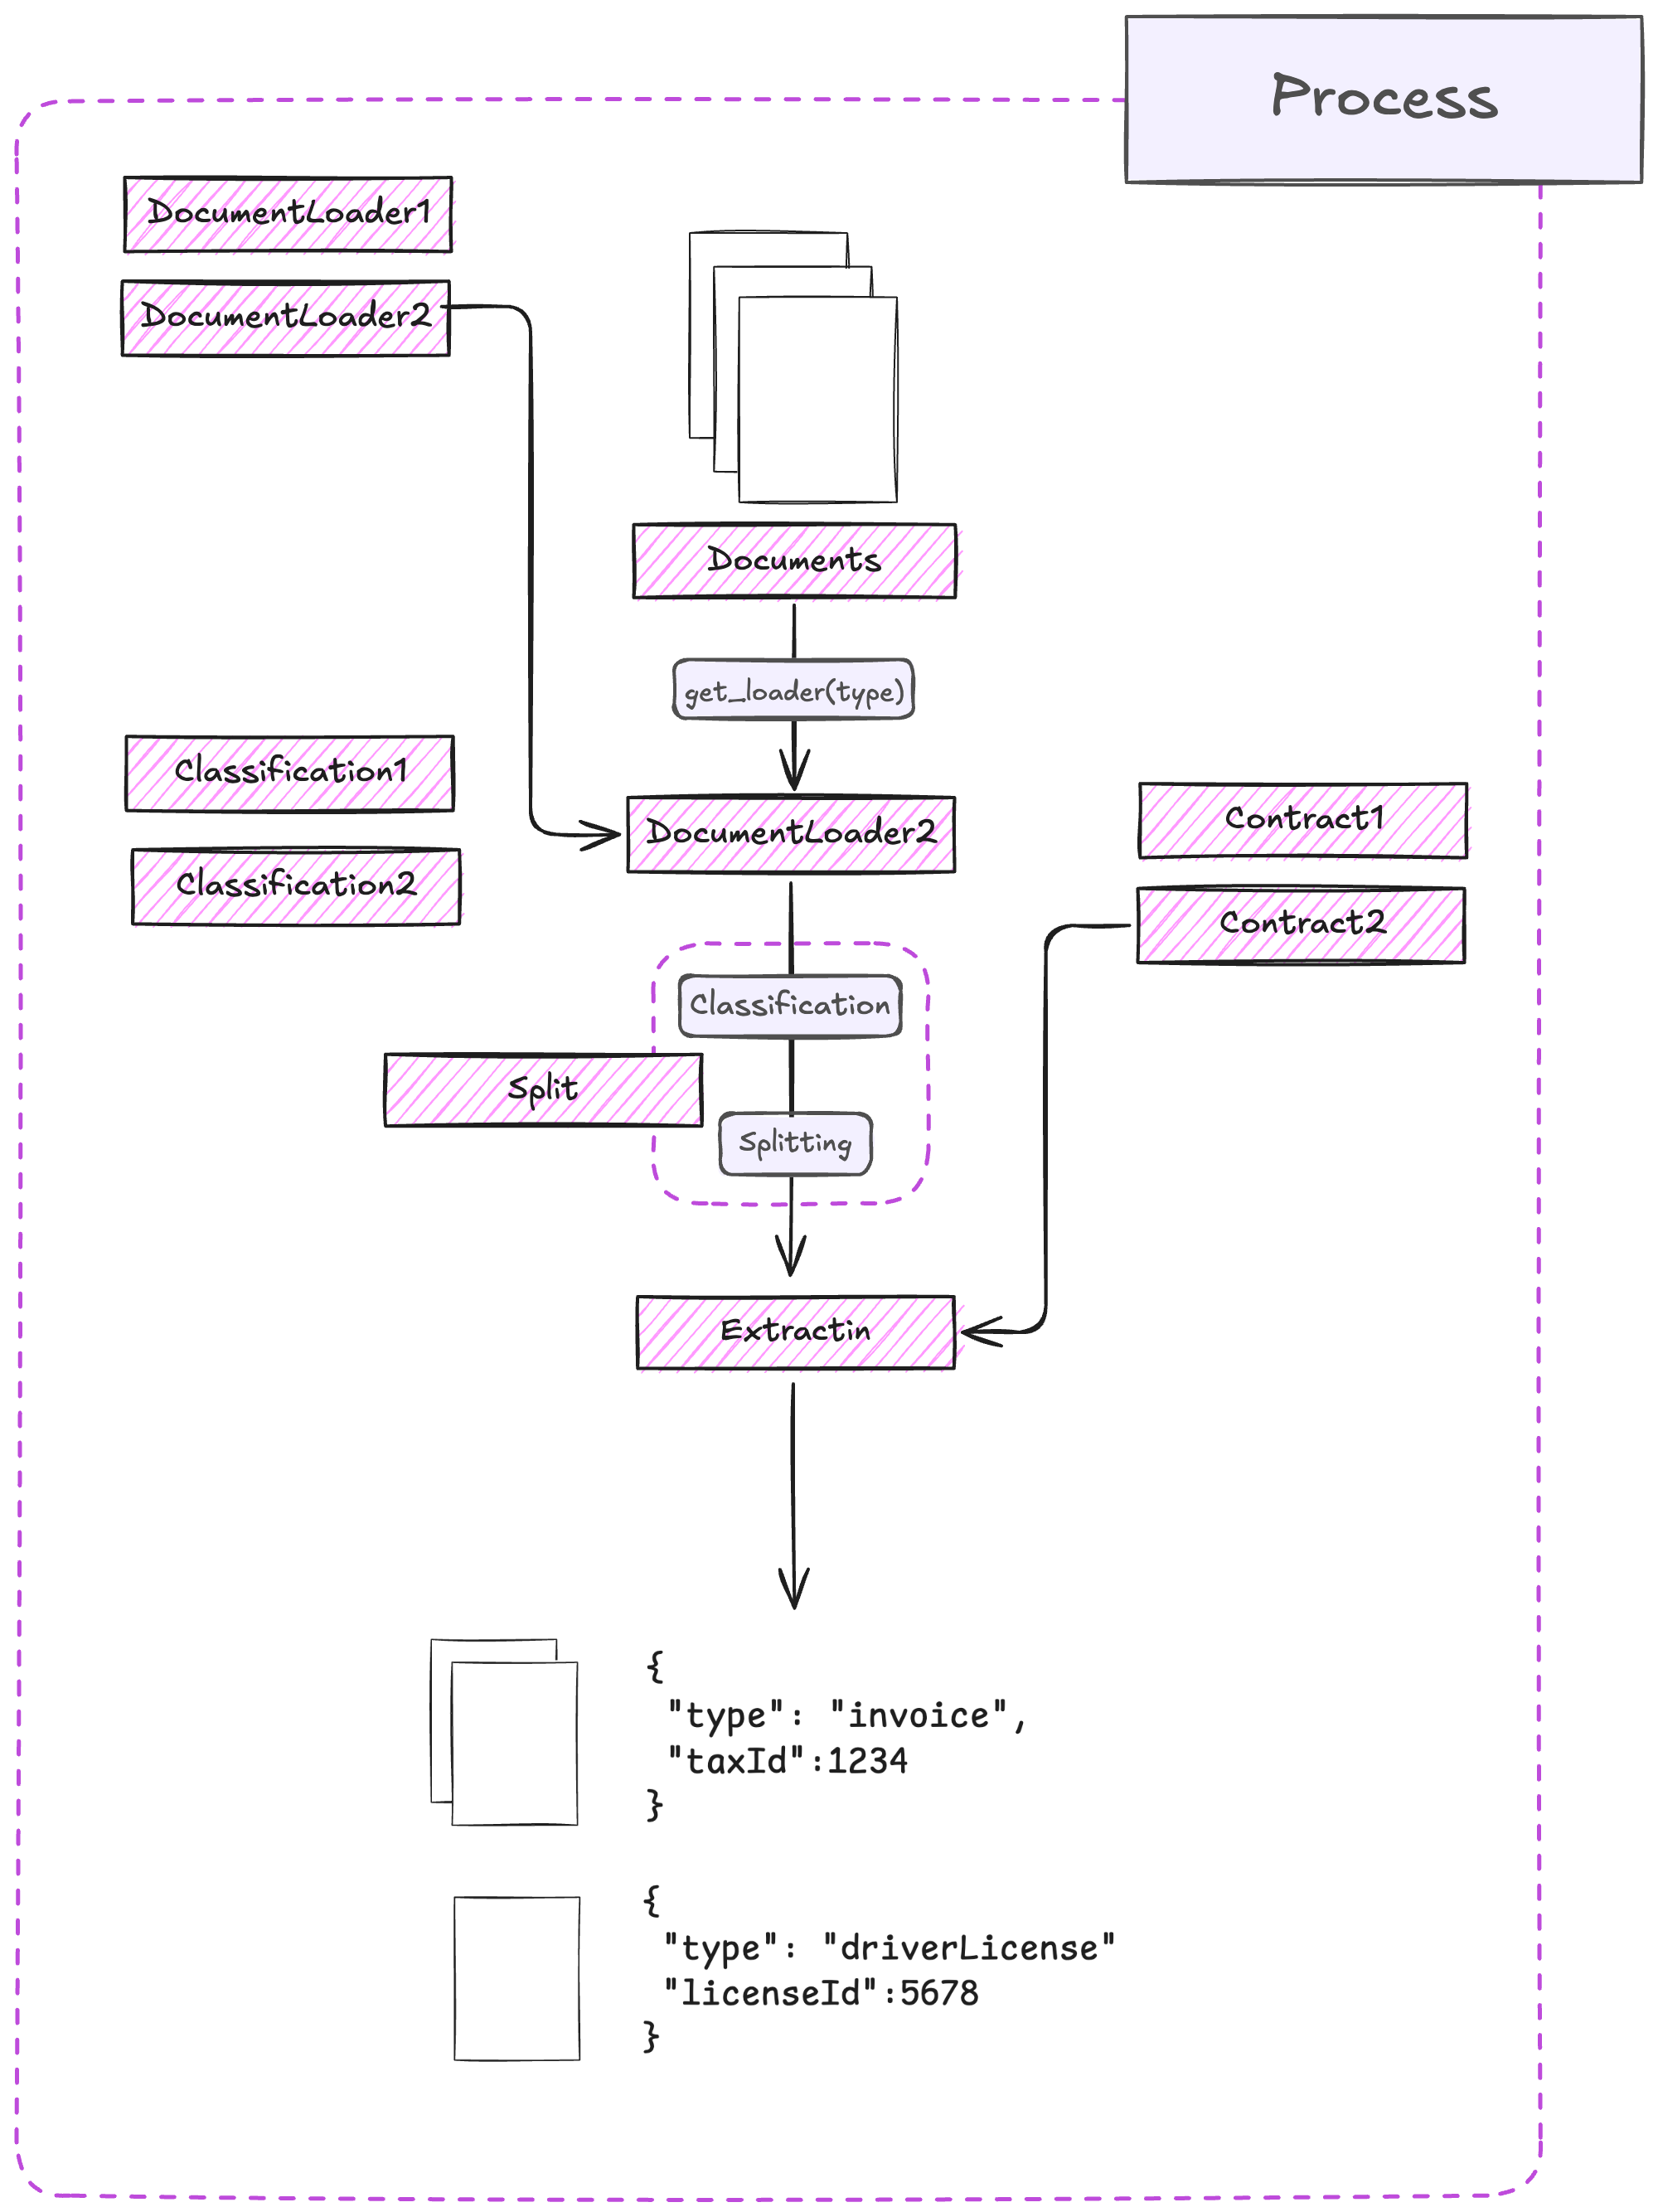
Your first extraction
Start with a small text invoice, verify loading without an API key, then extract a typed result. Python 3.9–3.13 is supported by the core library; the optional MCP service requires Python 3.10+.
Install
For the current release:
On Windows, activate with .venv\Scripts\activate. MIME detection uses system libmagic: brew install libmagic on macOS, or sudo apt-get install libmagic1 on Debian/Ubuntu. Windows installations may need python-magic-bin in place of the system library.
The 2026 additions are on the repository's main branch and are not yet a new PyPI release. To try them:
git clone https://github.com/enoch3712/ExtractThinker.git
cd ExtractThinker
python -m pip install -e .
Optional loaders need their own dependencies. For text PDFs, also install pypdf. For OCR, table parsing or cloud services, follow the selected loader's setup.
Check loading without a model
Create invoice.txt:
Then run:
from extract_thinker import DocumentLoaderTxt

pages = DocumentLoaderTxt().load("invoice.txt")
assert "INV-2026-001" in pages[0]["content"]
print(pages[0]["content"])
This checks installation and document loading. It makes no provider call.
Define the output and extract
Choose a model available to your account and set its provider credentials. The example reads EXTRACT_THINKER_MODEL so you can select a model without changing the script. Configure the API key expected by that provider, such as OPENAI_API_KEY, ANTHROPIC_API_KEY or GROQ_API_KEY.
import os
from pydantic import Field
from extract_thinker import Contract, DocumentLoaderTxt, Extractor, LLM

class Invoice(Contract):
    invoice_number: str
    supplier: str
    total: float = Field(ge=0)
    currency: str

extractor = Extractor(
    DocumentLoaderTxt(),
    LLM(os.environ["EXTRACT_THINKER_MODEL"], token_limit=1000),
)
result = extractor.extract("invoice.txt", Invoice)
print(result.model_dump())
Expected shape for the sample above (illustrative output, not a recorded model benchmark):
{
  "invoice_number": "INV-2026-001",
  "supplier": "Example Company",
  "total": 120.0,
  "currency": "EUR"
}
Extraction sends document content to the configured model and may incur provider charges. A validation failure raises; required fields are not silently filled with invented defaults.
Move to a PDF or image
For a text PDF, install pypdf and replace DocumentLoaderTxt() with DocumentLoaderPyPdf(). Pass your PDF path to extract. A scanned PDF needs OCR or vision; simply reading its text layer may produce no useful content.
For images, use a loader that supplies page images, a vision-capable model, and vision=True. See image loading. For larger inputs, read pagination and Ollama context limits.
Next steps
- Choose a document loader for your format and OCR needs.
- Add contract validation for application rules.
- Run the MCP service with Docker or a native Python process.
- Explore the 2026 additions and their compatibility notes.